Aisle 3No. 33 of 460
Splashery
ConvNet
620,030 small parts. Assembled in your browser.
Empty. Now look down.
Swipe across the pack to tear it open.
Press and hold. It pulls itself together.
Let go to drop it.
It stays in its pack here. The Playground has the rest.
AI and Computing · Built from a recipe
ConvNet
A convolutional network, or CNN, is a neural network built for pictures.
Play with it in the Playground
How to play
Tap it to read the digit. Draw your own digit in the Splash tab.
Toy facts
- Item
- No. 33 of 460
- Shelf
- Aisle 3, AI and Computing
- Kind
- Built from a recipe
- Small parts
- 620,030
- Your own
- Draw a digit
- Sound
- Yes
- Batteries
- None
- Assembly
- It does that itself
- Licenses
- CC BY 4.0
- Price
- $0.00
Small parts are the splats in its usual build on a computer. A phone may draw fewer.
Its controls
| Control | Kind | Range | Start |
|---|---|---|---|
| Read the digit | Tap | ||
| Read | Button | ||
| View | List | 3 choices | Poster (2D) |
About it
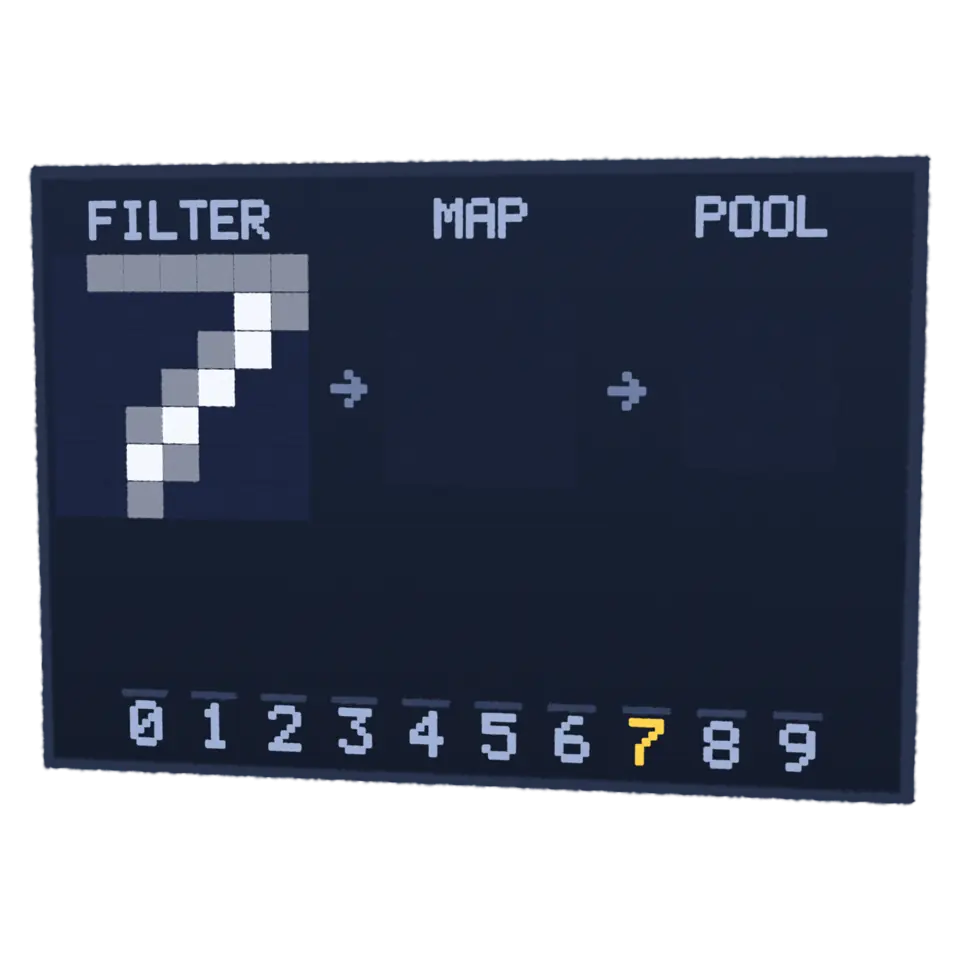
A convolutional network, or CNN, is a neural network built for pictures. It slides small filters across the picture: each filter is a little grid of weights that lights up where it finds its pattern, such as a slanted stroke, and makes a feature map. Pooling shrinks the map, keeping the strongest signal in each patch, and later layers combine the features to recognize the whole shape.
Tap it: a glowing 3-by-3 filter slides over a handwritten 7, stamping a feature map tile by tile; the tiles pool into a smaller map, and the scores for the digits 0 to 9 rise with 7 on top. In the Splash tab, pick a 3D view, or draw a digit and a small trained network reads it. Each square on the drawing pad is one pixel of the small 8-by-8 picture the network reads: the lighter its gray, the more ink it holds, and the pad starts with the sample 7.
Details
- Splats
- Opens at 200,000 at Mid Detail, 60,007 at Low, and up to 890,000 at Max
Is it right?
The drawing pad runs a real small convolutional network with stored trained weights. Its test-set result reproduces the displayed 97.0%. The separate 7 diagram uses real filtering and pooling but prepared final digit scores.
Correct
The drawing pad runs convolution, ReLU, pooling, dense scoring, and softmax.12
An independent tensor implementation matches every layer on ten samples and 64 random drawings to absolute error below 1e-10.
Correct
The network reads 8-by-8 images from a named digit dataset.3
The asset identifies UCI Optical Recognition of Handwritten Digits; pixel values are scaled from 0–16. All ten stored samples classify correctly.
Close
The displayed test accuracy is 97.0%.3
The exported network correctly classifies 1,743 of 1,797 original UCI test rows: 96.99499%, which rounds to 97.0%.
Correct
The introductory filter and pooling calculate feature values.12
The 3-by-3 cross-correlation and ReLU produce a 5-by-5 map. Max pooling includes smaller windows at the edges.
Simplified
The introductory digit scores are an illustration.1
The score array is stored separately from the filter and pooled values; its winning 7 is not inferred from that map.
- 1Convolutions for images, Dive into Deep Learning authors
- 2Pooling, Dive into Deep Learning authors
- 3Optical Recognition of Handwritten Digits, UCI Machine Learning Repository; Alpaydin and Kaynak
- Simplified
- The introductory diagram uses one fixed filter on a 7-by-7 sample, a normalized feature map, partial edge pooling windows, and stored digit scores. The drawing network reads 8-by-8 grayscale pixels and does not retrain while drawing.
Sources and credits
| Work | By | License |
|---|---|---|
| Optical Recognition of Handwritten Digits (UCI Machine Learning Repository) | E. Alpaydin and C. Kaynak (1998) | CC BY 4.0 |